Sylnovia
Sylnovia © 2026 · All Rights Reserved
Transmissions / Engineering Insight

Retrieval-Augmented Generation (RAG) Architecture: Building Enterprise AI Knowledge Bots

Date: October 13, 2026
•
Read Time: 3 Min Read
•
By: Sylnovia Labs
Retrieval-Augmented Generation (RAG) Architecture: Building Enterprise AI Knowledge Bots

Overcoming LLM Hallucinations with Grounded Knowledge

Large Language Models (LLMs) such as GPT-4, Claude, and Llama 3 possess incredible reasoning capabilities, but they suffer from two critical limitations in enterprise settings: their training data has a fixed knowledge cutoff, and they frequently hallucinate plausible-sounding falsehoods when asked about private corporate documentation or real-time data.

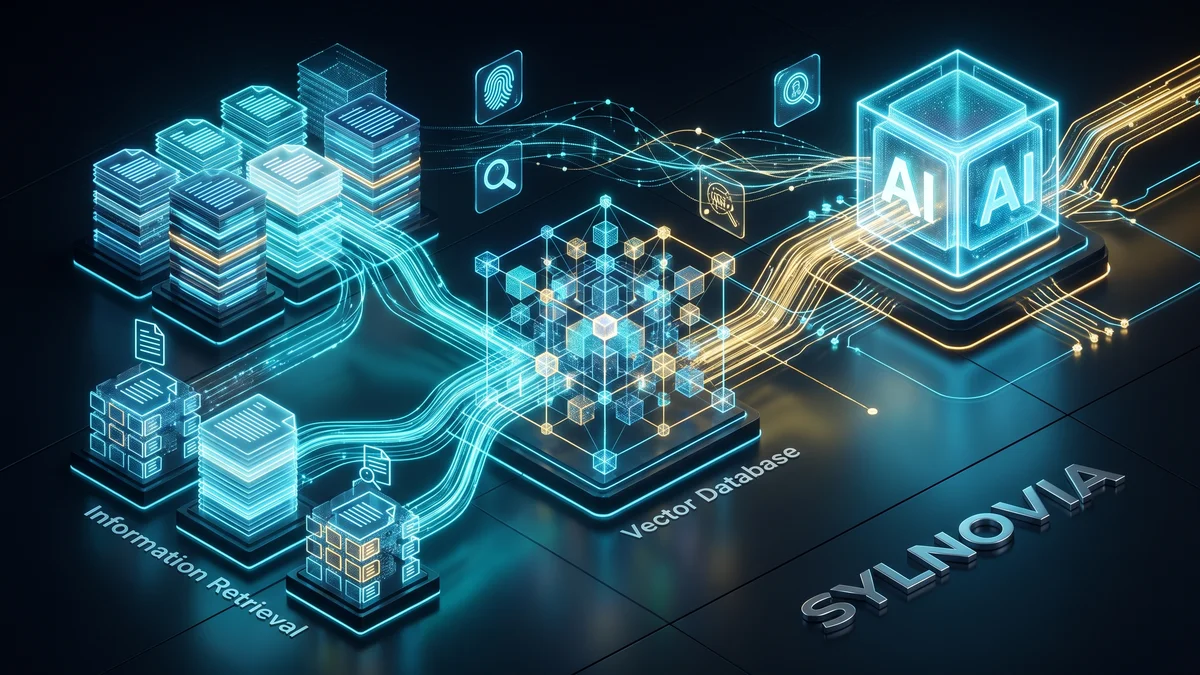
Retrieval-Augmented Generation (RAG) solves this fundamental challenge. Instead of retraining or fine-tuning models, RAG retrieves relevant proprietary documents from a vector database at query time and injects them into the model's context window as authoritative reference material, producing grounded, hallucination-free answers with precise source citations.

The Complete RAG Architecture Pipeline

  1. Document Ingestion & Chunking: Raw enterprise documents (PDFs, Notion pages, Google Docs, technical manuals) are ingested and partitioned into manageable chunks (e.g., 500–1,000 tokens) with semantic overlap to preserve contextual continuity across boundaries.
  2. Vector Embedding Generation: Each text chunk passes through an embedding model (such as OpenAI text-embedding-3-small or open-source HuggingFace models), converting text into high-dimensional numerical vectors (e.g., 1,536 dimensions) that encode semantic meaning.
  3. Storage in a Vector Database: Embeddings and metadata are indexed in specialized vector databases (such as Pinecone, Qdrant, Milvus, or PostgreSQL with the pgvector extension) optimized for approximate nearest neighbor (ANN) search.
  4. Semantic Retrieval at Query Time: When a user asks a question, the application embeds the user's query, executes a cosine similarity search against the vector index, and extracts the top 3–5 most relevant document chunks.
  5. Augmented Context Generation: The retrieved chunks and user query are formatted into a structured system prompt, instructing the LLM: "Answer strictly based on the provided context. If the answer is not contained within, state that you do not know."

Advanced RAG Optimization Techniques

  • Hybrid Search (Dense + Sparse): Pure vector search sometimes struggles with exact product SKUs, part numbers, or acronyms. Hybrid search combines semantic vector search with traditional BM25 keyword matching, merging results via Reciprocal Rank Fusion (RRF) for optimal accuracy.
  • Re-Ranking Models: Passing retrieved chunks through a cross-encoder re-ranking model (such as Cohere Rerank) re-scores chunks based on true contextual relevance, filtering out irrelevant noise before passing text to the LLM.
  • Metadata Filtering & Security ACLs: Ensure multi-tenant security by attaching tenant IDs and user access permission tags to document vectors, filtering results so employees only retrieve documents they are authorized to view.

Enterprise AI Integration with Sylnovia

At Sylnovia, we architect production-grade enterprise RAG pipelines with automated document synchronization, rigorous privacy guardrails, and sub-second retrieval latency. Contact our AI engineering team to build your organization's internal knowledge engine.

S

Published by Sylnovia Engineering

Delivering deep technical insights, architectural blueprints, and digital strategy for modern engineering squads.




